LM-agnostic Speech Encoders via Layer Granularity
Motivation
- Many studies analyze how different granularities of information are distributed across the layers of speech foundation models.
- In general, lower layers keep more acoustic features, while higher layers encode more linguistic and semantic information.
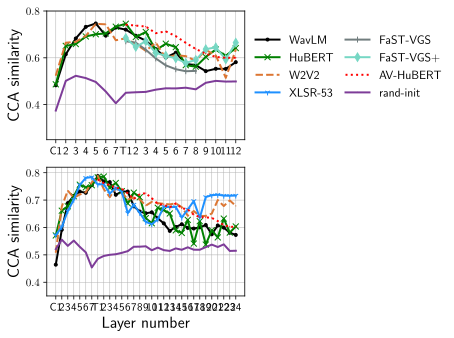
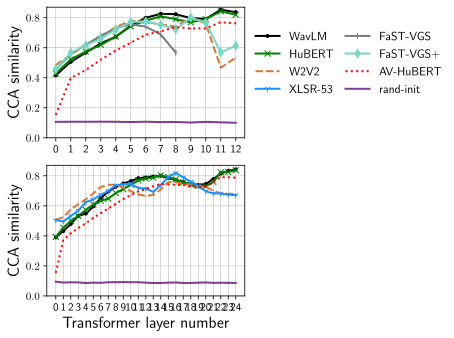
- Pasad et al. measure the canonical correlation analysis (CCA) similarity between each layer and spectrogram features, phone labels, and word labels across self-supervised speech models such as wav2vec 2.0, HuBERT, and WavLM [paper]
- Spectrogram (acoustic) similarity peaks in the CNN and the first Transformer layers, and then decreases.
- Phone similarity increases over the layers.
- Word similarity is low in the lower layers and peaks in the upper-middle layers.
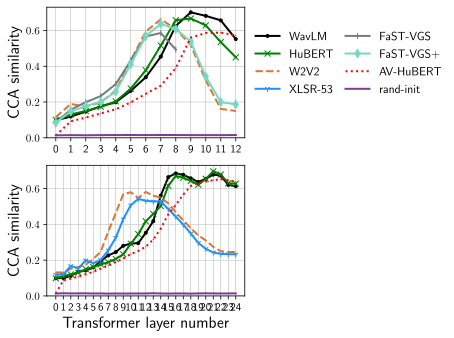
Figures 2–4 from Pasad et al. CCA similarity with spectrogram features, phone labels, and word labels for each layer (top: base models, bottom: large models).
- The trends depend on the pre-training objective. For example, in wav2vec 2.0, the last layers become less word-like again, so the top layer is not always the most linguistic one.
- They also find that the CCA trends are a reliable guide for choosing which layer to use for downstream tasks.
- A follow-up study extends the analysis beyond words to syntactic and semantic features across ten models, and finds that the pre-training objective and the model size heavily affect where this information is located [paper]
Matching Layers Across Modalities
- In line with the isomorphic geometry search, we also need to identify which layers encode information at the same granularity.
- A speech encoder layer that mostly encodes phones should be matched to a text model layer at a similar level, not simply the last layer of each model.
- For a speech LLM, this means aligning each layer of the speech encoder with the layer of the underlying LLM that has the matching granularity.
- If the alignment is based on granularity rather than on a specific LLM, the speech encoder could be reused across different LLMs.